JSON & RAG JSON
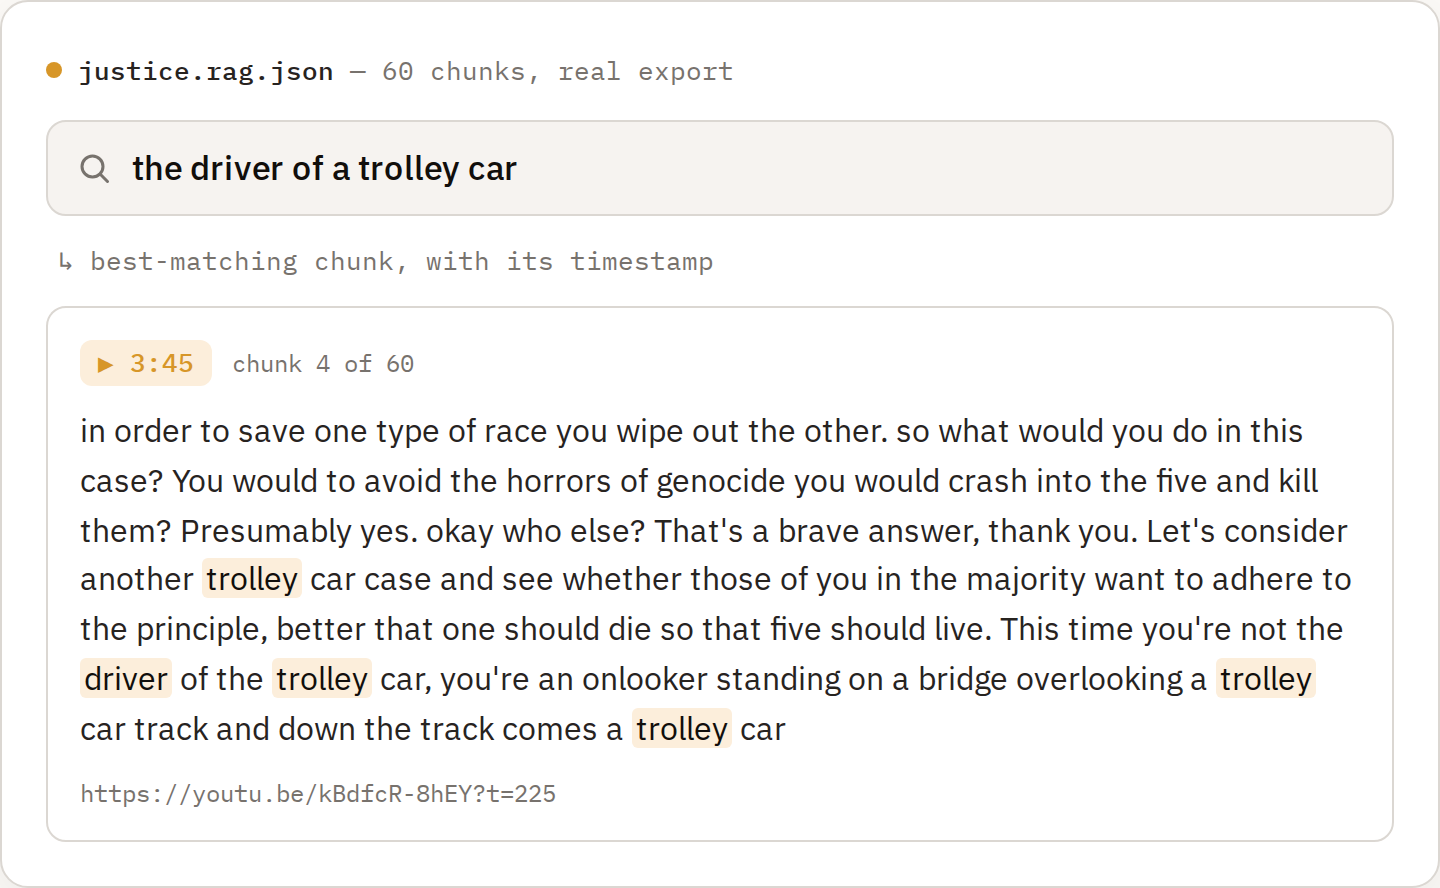
INDXR exports two kinds of JSON: standard JSON — the raw segments with a metadata wrapper, free — and RAG JSON — the transcript already cut into short passages (chunks) for RAG (retrieval-augmented generation, where an AI answers using text pulled from your own documents). Each chunk carries a token estimate (roughly how much of a model's input budget its text fills) and a deep link (a YouTube URL that jumps straight to that moment), ready to embed in a vector database — a store that finds passages by meaning rather than exact keywords.
Standard JSON (free)
A metadata wrapper around the transcript segments. Each segment has text, start_time and end_time (both in seconds; end_time is the next segment's start, or its own end for the last), plus a speaker when the transcript is diarised. The wrapper always carries video_id, title, duration_seconds and extracted_at, and adds channel, language, published_at and extraction_method when they are known (a video-file upload has no channel or publish date, so those are omitted). Take this when you want to handle the chunking and indexing yourself; it costs nothing on top of extraction.
{
  "metadata": {
    "video_id": "kBdfcR-8hEY",
    "title": "Justice: What's The Right Thing To Do? Episode 01 …",
    "duration_seconds": 3296,
    "extracted_at": "2026-08-07T15:18:48.032Z",
    "language": "en",
    "extraction_method": "youtube_captions"
  },
  "segments": [
    { "text": "Funding for this program is provided by:", "start_time": 4.2, "end_time": 8.24 },
    { "text": "Additional funding provided by", "start_time": 8.24, "end_time": 33.51 }
  ]
}
RAG JSON (chunked)
RAG JSON merges the segments into overlapping chunks and adds everything a retrieval pipeline needs. The top-level metadata.chunking_config records the chunk size, the overlap (about 15% of the chunk size), the overlap strategy, and the total chunk count.
Chunk fields
chunk_index/chunk_id— position and a stable id (<video_id>_chunk_000)text— the chunk text (including the overlap carried from the previous chunk)start_time/end_time— the chunk's time range in secondsdeep_link—https://youtu.be/<id>?t=N, jumps to the chunk's starttoken_count_estimate— words × 1.33metadata— video id, title, channel (nullwhen the source has no channel, e.g. a video-file upload), language, chunk index, total chunks, time range
Overlap strategy
For AI transcription the overlap snaps to whole sentences (overlap_strategy: sentence_boundary); for auto-captions it snaps to whole segments (segment_boundary). The example below is auto-captions, so chunk 1 opens by repeating the tail of chunk 0 ("…they will all die let's assume you know that for sure") — that repeated run is the overlap.
Chunk size presets
You choose the target chunk length when you export — 30, 60, 90, 120 seconds. Sixty seconds is the default. Shorter chunks are tighter and better for pulling exact quotes; longer chunks keep more surrounding context per vector. Your preferred size is remembered in Settings.
Scroll the table horizontally →
Costs credits
RAG JSON costs 1 credit per 10 minutes of transcript (minimum 1). Standard JSON and the other formats are free. Re-downloading a transcript you already exported to RAG JSON is free.{
"metadata": {
"video_id": "kBdfcR-8hEY",
"title": "Justice: What's The Right Thing To Do? Episode 01 …",
"duration_seconds": 3296,
"extracted_at": "2026-08-07T15:18:48.032Z",
"chunking_config": {
"chunk_size_seconds": 60,
"overlap_seconds": 9,
"overlap_strategy": "segment_boundary",
"total_chunks": 60
},
"language": "en",
"extraction_method": "youtube_captions"
},
"chunks": [
{
"chunk_index": 0,
"chunk_id": "kBdfcR-8hEY_chunk_000",
"text": "Funding for this program is provided by: Additional funding provided by This is a course about Justice … they will all die let's assume you know that for sure",
"start_time": 4.2,
"end_time": 65.08,
"deep_link": "https://youtu.be/kBdfcR-8hEY?t=4",
"token_count_estimate": 128,
"metadata": {
"video_id": "kBdfcR-8hEY",
"title": "Justice: What's The Right Thing To Do? Episode 01 …",
"channel": null,
"chunk_index": 0,
"start_time": 4.2,
"end_time": 65.08,
"language": "en",
"total_chunks": 60
}
},
{
"chunk_index": 1,
"chunk_id": "kBdfcR-8hEY_chunk_001",
"text": "that if you crash into these five workers they will all die let's assume you know that for sure and so you feel helpless … how many would turn the trolley car onto the side track?",
"start_time": 56.78,
"end_time": 118.18,
"deep_link": "https://youtu.be/kBdfcR-8hEY?t=56",
"token_count_estimate": 150,
"metadata": { "…": "same shape as chunk 0" }
}
]
}
Sources
- INDXR (own code) — standard JSON metadata wrapper + segment fields (text, start_time, end_time)Verified against packages/shared/src/utils/formatTranscript.ts (generateJson)
- INDXR (own code) — RAG JSON schema, chunking, overlap, deep links, token estimateVerified against packages/shared/src/utils/formatTranscript.ts (buildRagJson, buildRagChunks)
- INDXR (own code) — chunk-size presets (30/60/90/120s, default 60) and token estimatesVerified against packages/shared/src/lib/pricing.ts (RAG_CHUNK_PRESETS)
- LangChain / Pinecone / ChromaDB / Weaviate / Qdrant — the vector databases the chunk shape targets