Limits
INDXR enforces a few hard limits: AI transcription up to 10 hours per file, uploads up to 500 MB, playlists up to 500 videos per job (a job is one transcription or playlist run), and 3 jobs running at once. Caption extraction — pulling a video's existing subtitles — has no length limit, and requests are rate-limited (each account can only make so many per hour). There is no public REST API, the kind of programmatic interface other apps could plug into.
Size & length
Scroll the table horizontally →
Audio over 10 hours is rejected before any credits are reserved — you are never charged for a file the provider can't process. A playlist over 500 videos is rejected the same way; split it into batches of 500. “Concurrent jobs” means how many transcriptions or extractions can run at the same time — you can have up to 3 going at once.
Library storage
Your library — every saved transcript plus its edits, AI summaries and exported files — has its own storage cap. This is separate from the per-file upload size above: the upload cap limits a single file you send in, while this limits the total size of everything kept in your library. Because transcripts are text, 100 MB holds a great many of them.
Scroll the table horizontally →
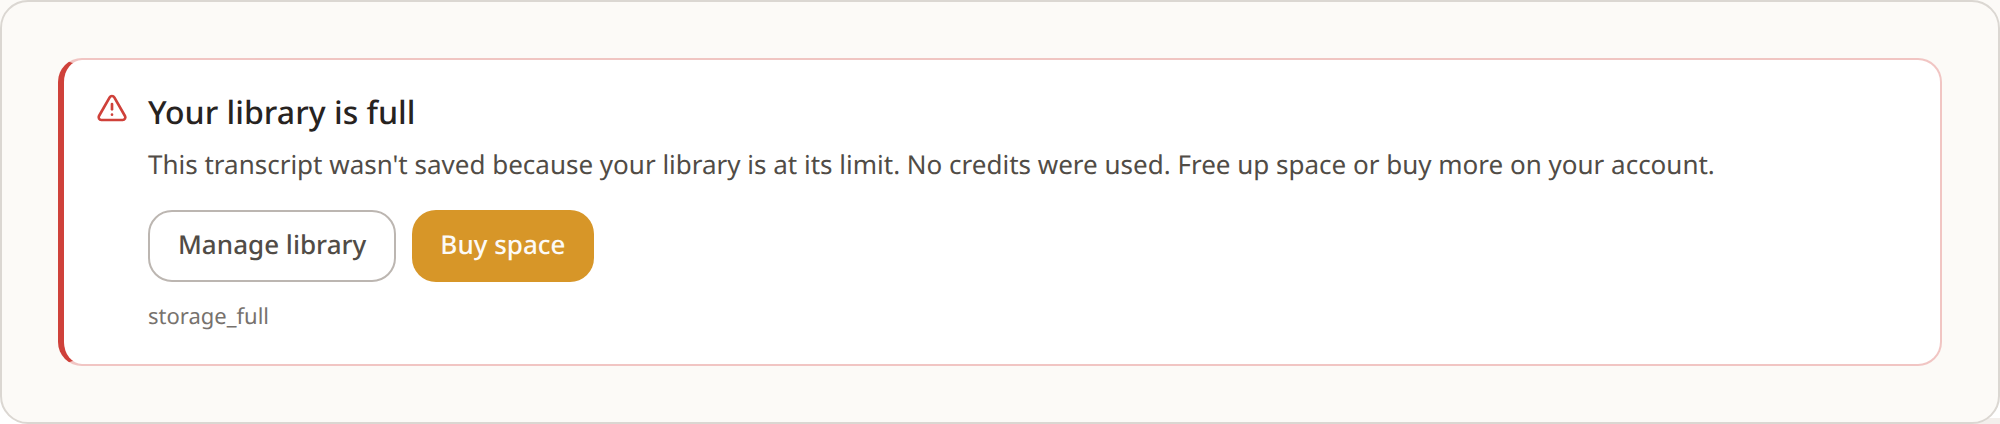
When your library is full, a new transcript is refused before any credits are reserved — you are never charged for a transcript that could not be saved, and your existing transcripts are left untouched. Free up space by deleting transcripts you no longer need, or buy more room: 100 credits adds a permanent 100 MB, up to a 500 MB total. See Credits for how buying space works.
Rate limits
A rate limit caps how many requests you can make in a set window of time, so no single user can overload the service. “Per IP” means per network address — how visitors without an account are counted.
Scroll the table horizontally →
Not enforced right now. These rate limits describe how requests will be capped once the limiter is switched on. It is currently off in production, so no request is rate-limited today — treat the numbers above as the intended limits, not the current behaviour.
No public API
INDXR is a web app — there is no public REST API, the kind of endpoint other programs could call directly to automate it. Everything runs through the interface; the export formats (including JSON and RAG JSON) are how you get the data out programmatically — that is, into your own scripts or tools.
Sources
- INDXR (own code) — duration, playlist, concurrency and upload limitsVerified against backend/main.py (MAX_TRANSCRIPTION_SECONDS, MAX_PLAYLIST_VIDEOS, MAX_CONCURRENT_JOBS); backend/audio_utils.py (SUPPORTED_FORMATS, MAX_FILE_SIZE_MB); packages/shared/src/lib/limits.ts (TS mirror, sync-checked)
- INDXR (own code) — library storage base, maximum, buy-space ratio and full-library enforcement (ADR-078)Verified against packages/shared/src/lib/storage.ts; supabase migrations 20260723140000_library_storage_limit, 20260724013956_library_storage_max_cap; backend is_library_full
- INDXR (own code) — rate limits and the after-purchase bypassVerified against packages/shared/src/lib/ratelimit.ts; apps/marketing/src/app/api/extract/route.ts
See also